Two requests. No credentials. And a crash that lands on whichever member wins the next election.
That is the shape of CVE-2026-118383, a use-after-free in MongoDB Server that Datadog Security Labs reproduced in a lab and published yesterday. MongoDB rated it 9.5 out of 10 on the CVSS 4.0 scale, and released fixed versions earlier this week.
The flaw is not a straightforward "send packet, get crash." It requires a chain of events, and understanding that chain is what tells you whether you are exposed and how urgently you need to move.
How the Chain Actually Works
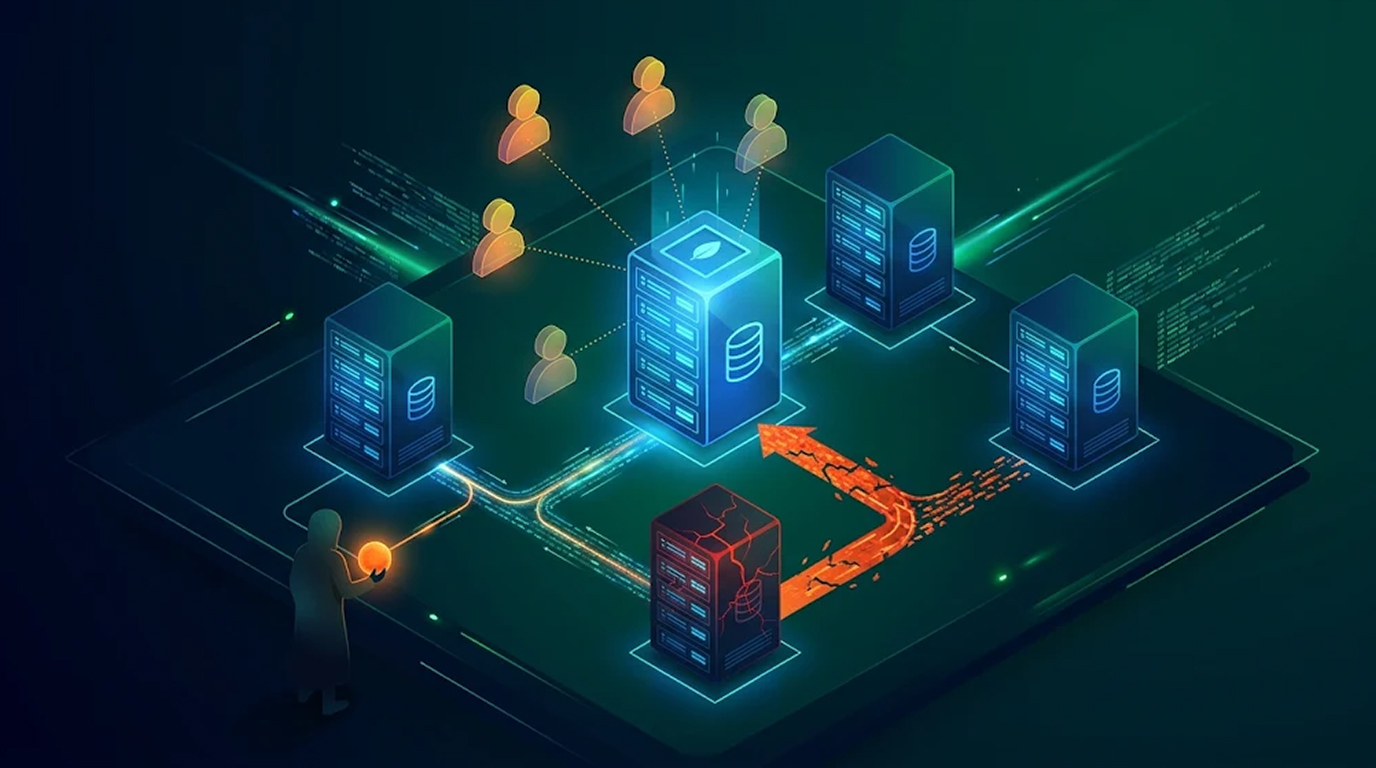
Start with the architecture. The affected servers are members of a replica set, a group of MongoDB servers holding copies of the same data. One member is the primary, and it handles all new writes. The others replicate those writes and wait.
If the primary becomes unavailable, the remaining members hold an election and pick a new primary.
Here is where the flaw lives. A member that wins an election while it is behind on replication has to catch up first, applying the writes it missed before it accepts any new ones. The bug sits in the cleanup that runs when that catch-up step ends.
The two requests are ping commands carrying a readConcern.afterOpTime value. Each one asks the server to wait until replication reaches a certain point, and the server records a pending notification for it. The researchers call these waiters.
Planting the waiters does not crash anything. They do not expire. They sit there until the member restarts, rolls back, or steps down from primary.
The crash comes later. When catch-up ends on a member that received those requests, the cleanup runs twice. The second run touches memory that was already freed, and the new primary crashes before it accepts a single write.
What the Attacker Can and Cannot Control
This is where the flaw gets less scary and more interesting at the same time.
The attacker cannot make the targeted member fall behind. It cannot make that member win an election. It cannot see when either happens. Datadog was explicit about all three.
What the attacker can do is plant waiters and wait. The crash fires if the right member wins the next election at the right time.
Once those conditions line up, the crash does not depend on winning a timing race. That is the researchers' point. The hard part is the election, not the microseconds.
|
Attacker Controls |
Attacker Does Not Control |
|
Sending the two ping requests |
Whether the member falls behind |
|
Planting waiters that persist |
Whether the member wins an election |
|
Nothing else |
When any of it happens |
Authentication Does Not Help
Turning on authentication does not stop the two requests on vulnerable versions.
That is a detail worth repeating, because it is the assumption most administrators would make first. A locked-down database is not protected from this.
In the lab, the researchers only used admin access to pause and stop mongod processes, which let them force the failover and make a member fall behind. The two requests themselves came from a client with no credentials, and that client could not write to the database.
The Affected Scope
Affected members include the shard and config server members of sharded clusters. A standalone mongod outside any replica set is not affected.
Every earlier version in a branch is affected, back to that branch's first release. MongoDB says it found the flaw itself and is "not aware of any attempts to take advantage of this vulnerability."
MongoDB Atlas clusters receive fixed versions automatically during maintenance. Customers who defer maintenance should apply the upgrade as soon as possible.
Self-managed deployments need the fixed release on every replica set member. That includes members running in containers, and members that were offline during the maintenance window. Check the running version on each one after upgrading rather than trusting the rollout.
The 8.2 Branch Problem
The 8.2 branch is not among the affected versions listed, and its newest release is 8.2.12. That looks like a clean bill of health.
It is not quite that simple. A proof of concept published on GitHub reports that 8.2.12 still exhibited the bug in a lab test, using a test-only setting.
And the 8.2 branch reached end of life on July 31. Past that date, a version stops receiving fixes, including security fixes. If you are running 8.2, you are outside support regardless of what this advisory says.
What the Fix Actually Changes
Two things, according to the researchers.
The first lets only system users use readConcern.afterOpTime. In the lab, that is why fixed 8.0.37 rejected both requests as unauthorized immediately, and the member kept running.
The second stops the cleanup from running twice even when waiters are already in place. The researchers did not test that part themselves. In the proof-of-concept lab test, which ran with authentication off, fixed 8.0.37 accepted the planted waiters but ran the cleanup only once.
Code Execution: Possible, Not Demonstrated
MongoDB says the flaw may also result in arbitrary code execution in the server process under certain conditions.
Datadog did not get there. Their results state plainly that "we did not achieve code execution," and they do not show how often the attack would work in other setups.
The public proof of concept describes its impact as a crash or memory corruption, with no claim of code execution. Its reliable mode requires a test-only setting that a remote attacker cannot enable.
Treat the code execution claim as a vendor assessment that has not been independently reproduced. The crash, on the other hand, is demonstrated.
What the Lab Crash Looked Like
On version 8.0.34, the member crashed with a segmentation fault, leaving the lab cluster without a primary.
Another deployment might elect a new primary and keep running after the crash. That depends on cluster size, configuration, and how quickly the remaining members react. The lab result is one data point, not a universal outcome.
Detection: What to Look For in the Logs
The researchers published specific log signs from their vulnerable run.
|
Indicator |
Detail |
|
Slow query (ID 51803) |
A COMMAND entry for an unauthenticated ping carrying readConcern.afterOpTime that ended with MaxTimeMSExpired |
|
Primary catch-up (ID 21359, 21363) |
A member entering primary catch-up, then exiting it twice in one transition |
|
Crash signature |
A fatal signal or backtrace involving CatchupState::abort_inlock() after those exits |
A normal election, or a single catch-up exit, does not point to this flaw. And the requests may arrive well before the failover, so check earlier logs from the same member too.
Two caveats on log review. Whether the request fields get logged depends on your logging settings. And the attr.remote field may show a loopback address instead of the client's real IP, which makes attribution harder.
The Interim Mitigation
Until a member can be upgraded, the researchers advise restricting network access to the database to only the systems that need it.
That limits who can send the two requests. It does not fix the flaw. Anyone already inside the permitted network still has the path.
What Administrators Should Do
- Upgrade every replica set member. Not just primaries. Every member, including containerized ones and any that were offline during the rollout.
- Check the running version after the upgrade. Query each member and confirm. A completed deployment job is not the same as a confirmed version.
- Look up your branch's fixed release in the CVE record. Each branch has one, and every earlier release in the branch is affected.
- Apply Atlas maintenance rather than deferring it. Clusters receive fixes automatically, but only when maintenance runs.
- Plan an exit from 8.2. It is past end of life and will not receive fixes.
- Restrict network reach in the meantime. Allow only the systems that genuinely need to talk to the database.
- Review logs for the three indicators. Especially the double catch-up exit, which is the clearest single signal in the chain.
- Do not assume authentication protects you. It does not, on vulnerable versions.
FAQ
What is CVE-2026-118383?
A use-after-free in MongoDB Server rated 9.5 on CVSS 4.0. An unauthenticated attacker can plant waiters with two ping requests, and the crash fires if that member later wins an election while behind on replication.
Does authentication stop the attack?
No. On vulnerable versions, turning on authentication does not stop the two requests.
Can the attacker force the crash?
Not directly. They cannot make the target fall behind, cannot make it win an election, and cannot see when either happens. They plant waiters and wait for the conditions.
Which deployments are affected?
Replica set members, including shard and config server members of sharded clusters. A standalone mongod is not affected.
Which versions are fixed?
Each affected branch has its own fixed release, listed in the CVE record and MongoDB's announcement. In the researchers' lab, 8.0.34 was vulnerable and 8.0.37 was fixed.
What about MongoDB 8.2?
It is not listed among the affected versions, but a public proof of concept reports that 8.2.12 still exhibited the bug in a lab test using a test-only setting. The branch also reached end of life on July 31, so it will not receive fixes.
Can this lead to code execution?
MongoDB says it may, under certain conditions. Datadog did not achieve code execution in the lab, and the public proof of concept claims only a crash or memory corruption.
How do I detect an attempt?
Look for log ID 51803 with an unauthenticated ping carrying readConcern.afterOpTime that ended in MaxTimeMSExpired, then a member entering catch-up (ID 21359) and exiting it twice (ID 21363) in one transition, followed by a fatal signal involving CatchupState::abort_inlock().
Is there a workaround?
Restricting network access to the database limits who can send the requests. It does not fix the flaw.
Has anyone exploited it in the wild?
MongoDB says it is not aware of any attempts to take advantage of the vulnerability.